
 Web Development
 Data Science
 Python
 SQL
 JavaScript
 Artificial Intelligence
 IT & Software
 IT Certifications
 Hacking
 AWS
 Arduino
 DevOps
 3D Modeling
 Graphic Design
 Photoshop
 Drawing
 Digital Painting
 UX Design
 Business
 Data Analysis
 Communication Skills
 Project Management
 Leadership & Management
 Human Resources
 Digital Marketing
 Social Media Marketing
 Marketing
 SEO
 Google Analytics
 Branding
 Excel
 Office Productivity
 SAP
 PowerPoint
 Microsoft Access
 SharePoint
 Finance & Accounting
 Trading & Investing
 Accounting
 Bitcoin
 Personal Finance
 Video Editing & Animation
 Photography
 Adobe Premier Pro
 Adobe Lightroom
 Personal Development
 Productivity
 Career Development
 Life Coaching
 Health & Fitness
 Meditation & Mindfulness
 Yoga
 Music
 Music Production
 Guitar
 Piano
 Singing
 Language Learning
 Teaching & Academics
 Engineering
 Math
 Lifestyle
Real Time Spark Project for Beginners: Hadoop, Spark, Docker (Udemy.com)
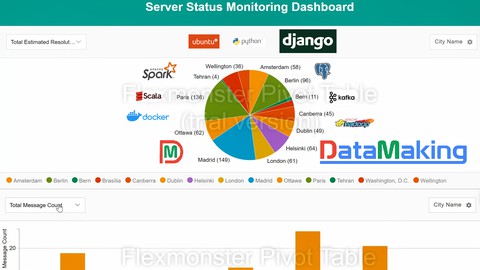
Building Real Time Data Pipeline Using Apache Kafka, Apache Spark, Hadoop, PostgreSQL, Django and Flexmonster on Docker
Created by: PARI MARGU
Last updated October 2020
 What you will learn
- Complete Development of Real Time Streaming Data Pipeline using Hadoop and Spark Cluster on Docker
- Setting up Single Node Hadoop and Spark Cluster on Docker
- Features of Spark Structured Streaming using Spark with Scala
- Features of Spark Structured Streaming using Spark with Python(PySpark)
- How to use PostgreSQL with Spark Structured Streaming
- Basic understanding of Apache Kafka
- How to build Data Visualisation using Django Web Framework and Flexmonster
- Fundamentals of Docker and Containerization
How it compares
Against the other 150 rated Udemy courses in Hadoop on CourseDuck:
- Rating3.7 out of 5higher than 10% of them
- Reviews96#114 of 151 by number of reviews
- Length6.6 hourslonger than 55% of them
- Last updatedOctober 2020earlier than 67% of them
 Course Description
In many data centers, different type of servers generate large amount of data(events, Event in this case is status of the server in the data center) in real-time.
There is always a need to process these data in real-time and generate insights which will be used by the server/data center monitoring people and they have to track these server's status regularly and find the resolution in case of issues occurring, for better server stability.
Since the data is huge and coming in real-time, we need to choose the right architecture with scalable storage and computation frameworks/technologies.
Hence we want to build the Real Time Data Pipeline Using Apache Kafka, Apache Spark, Hadoop, PostgreSQL, Django and Flexmonster on Docker to generate insights out of this data.
The Spark Project/Data Pipeline is built using Apache Spark with Scala and PySpark on Apache Hadoop Cluster which is on top of Docker.
Data Visualization is built using Django Web Framework and Flexmonster.
Apache Spark is an open-source unified analytics engine for large-scale data processing. Spark provides an interface for programming clusters with implicit data parallelism and fault tolerance.
Apache Kafka is a distributed event store and stream-processing platform. It is an open-source system developed by the Apache Software Foundation written in Java and Scala. The project aims to provide a unified, high-throughput, low-latency platform for handling real-time data feeds.
Apache Hadoop is a collection of open-source software utilities that facilitates using a network of many computers to solve problems involving massive amounts of data and computation. It provides a software framework for distributed storage and processing of big data using the MapReduce programming model.
A NoSQL (originally referring to "non-SQL" or "non-relational") database provides a mechanism for storage and retrieval of data that is modeled in means other than the tabular relations used in relational databases.

 Udemy Discount
The discount is applied through our link. Open the course from here and Udemy's current promotional price is applied at checkout on most courses, no code to type.
Some courses are excluded from Udemy's promotions. If the price does not drop, clear your browser cookies and use the button again.
Instructor Details
- 3.7 Rating
 96 Reviews
PARI MARGU
Data Engineer(Big Data/Hadoop, Apache Spark, Python) cum Freelance Consultant, YouTube Creator. Having 12+ years of experience in implementing solutions to the enterprise clients and having strong Framework skills to implement complex business solutions. Worked on, Web, Windows, Mobile and Hadoop/Big Data, Apache Spark applications. Having 6+ years of experience with Hadoop/Big Data, Apache Spark Framework. Worked on Hadoop distributions like Cloudera CDH, Apache Hadoop.
 More courses by PARI MARGU
Spark Project on Cloudera Hadoop(CDH) and GCP for Beginners (2021)
3.7 (124 Reviews)
 Provider: Udemy
 Time: 10.9h
$54.99
Apache Spark Project for Beginners: A Complete Project Guide (2020)
4.1 (62 Reviews)
- Provider: Udemy
- Time: 2.5h
$10.99
More Hadoop courses
Spark Streaming - Stream Processing in Lakehouse - PySpark (2024)
4.9 (2,251 Reviews)
- Provider: Udemy
- Time: 22.4h
$11.99
Apache Kafka Series - KSQL on ksqlDB for Stream Processing ! (2026)
4.9 (2,161 Reviews)
- Provider: Udemy
- Time: 4h
$12.99
Apache Kafka Series - Kafka Streams for Data Processing (2026)
4.8 (6,826 Reviews)
- Provider: Udemy
- Time: 4.8h
$14.99
Apache Kafka Series - Confluent Schema Registry & REST Proxy (2026)
4.8 (3,794 Reviews)
- Provider: Udemy
- Time: 4.5h
$94.99

Apache Kafka - Real-time Stream Processing (Master Class) (2023)
4.8 (2,925 Reviews)
- Provider: Udemy
- Time: 11h
$10.99

Apache Spark 3 & Big Data Essentials in Scala (2024)
4.8 (2,302 Reviews)
- Provider: Udemy
- Time: 7.3h
$39.99
 Reviews

By Samuel Kumar on 8/29/2024
Very simple explanation, though it's from the early age of docker era but still the tutor has explained the concept wonderfully.
By Sushant Bisht on 4/19/2022
the instructor's voiceover is too fast with poor voice modulation. Between most of the chapters, I was forced to increase/decrease volume depending upon the instruction's voice. The concepts are not explained properly and the focus seemed more on the mechanics.
By Khristian Schönrock on 3/25/2022
Audio is terrible, the presentation is lacking. Subtitles would have been extremely helpful.
By Aditya Venkat Madugundu on 1/26/2022
Good high level overview of Apache Spark and its advantages over Hadoop and MapReduce.
By Brendan Farragher on 8/11/2021
Extremely difficult to understand what is being said
By Sneha Morakhia on 4/10/2021
Excellent course. Highly recommended for people who want to start from scratch.
By T O on 1/24/2021
I liked the course content but the sound quality isn't good, which makes it difficult to understand the content.
By Edoardo Carbone on 10/18/2020
Every section is described in depth and it helped tremendously practicing with a proper application of this topics to fully understand them. Also, Pari was totally available for any question or issues I had!
By Biraj Parikh on 10/14/2020
It's one of the best course ever which demonstrates an end-to-end ETL pipeline covering the latest big data technologies like Spark Structured Streaming, Apache Kafka, PostgreSQL, Django, Docker, etc. Also, I had an interview recently in which I demonstrated this project, and as expected the interviewer was fully impressed when I showcased the project. Thank you so much, Pari sir I had a great time learning about the course content and really enjoyed your detailed explanation covering the use-case and working with different components. Furthermore, I had issues setting up the docker and other services on my windows machine, and Pari Sir offered me a personal help and we scheduled a Zoom video call to help setup my machine and after some troubleshooting, he managed to setup the entire docker containers and services for me. I would highly recommend this course to anyone who is looking for a Data Engineering role and wants to work on an end-to-end pipeline. PS: I bagged an offer from a Top Consulting company as a Data Engineer.
By Saqib Saqib on 10/5/2020
course is really great and worth watching and a good skill to add
 Quality Score
No CourseDuck member has rated this course yet. Taken it? Give each part a thumbs up or down.
Overall Score : 74 / 100
- Video Duration:
 6.6h
- Price: $44.99
- Provider: Udemy
- Updated:
 October 2020
- Level:
 All Levels
- Language:
 English
- Certificate:
 Yes
30-day money-back guarantee on most paid courses
Udemy Coupon Price Tracker
